

F-Secure maps 26 AI harms in consumer safety taxonomy
Wed, 18th Nov 2026 (Today)
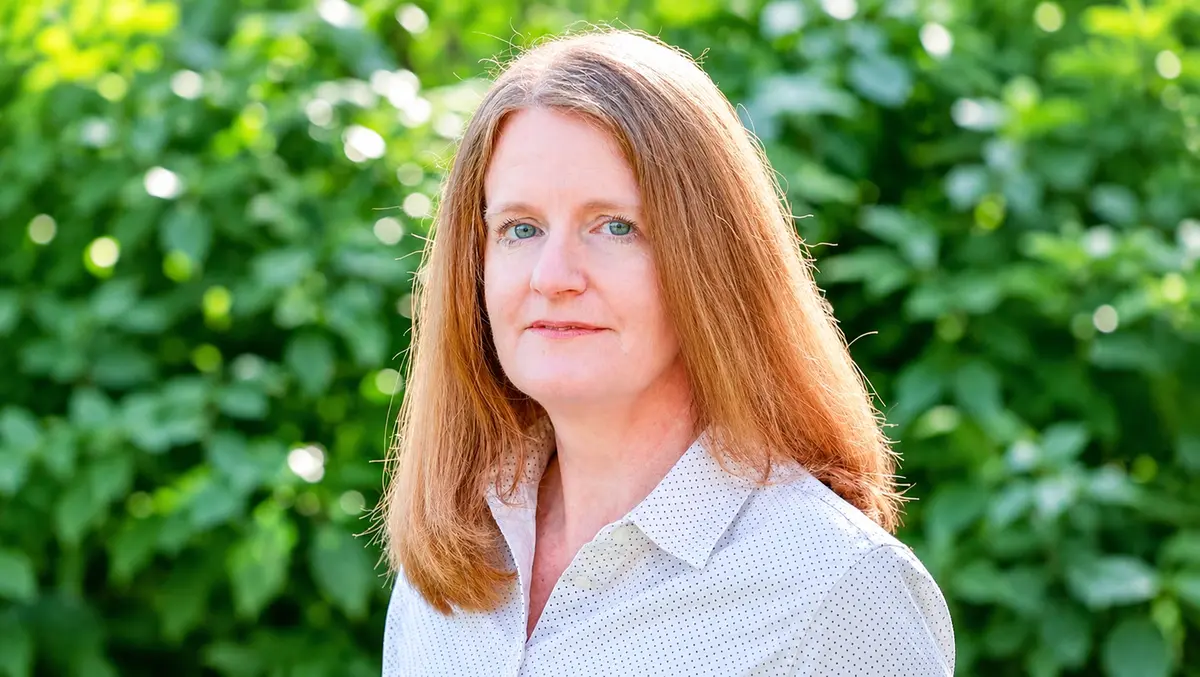
F-Secure has published an AI Harms Taxonomy that sets out 26 ways artificial intelligence can harm consumers. Developed by Dr. Megan Squire, Principal Threat Intelligence Researcher at F-Secure, the framework traces how harm can move through AI systems before reaching a person.
It maps 19 intermediary layers and identifies 24 possible defences. The risks it covers range from misleading chatbot responses to voice and video impersonation, harmful financial decisions by agents, exposure of personal information, and attacks that hide malicious instructions in content processed by AI systems.
F-Secure says the taxonomy is designed to show not only what can go wrong, but also where intervention is possible and which parties are in a position to act. Responsibility for prevention, it argues, is spread across device-level protections, AI product developers, and the operators of the wider systems connected to those tools.
Dr. Squire said many discussions of AI risk focus on listing potential harms without linking them to the technical systems and organisations that could stop them. This framework instead follows the path from an AI-enabled threat to its effect on a consumer, showing where safeguards could be put in place.
"As AI systems become more capable, the consequences of their mistakes can extend well beyond a bad answer," said Dr. Megan Squire, Principal Threat Intelligence Researcher at F-Secure.
"The people building them have a responsibility to understand how they can fail and who gets hurt when they do, and to put safeguards in place before that harm happens," she said.
Changing risks
The taxonomy reflects a shift in how digital threats reach consumers. Rather than a criminal targeting a person directly, AI systems can now sit between the attacker and the victim, creating more points of failure and widening the number of participants involved.
That change is particularly relevant as AI tools move from generating text and answers to taking actions on a user's behalf. A chatbot that returns an incorrect response may mislead a person who can still review the output. An autonomous agent with access to linked services and accounts, however, could carry out harmful actions without the same degree of human oversight.
Examples highlighted in the research include systems acting on outdated context, exposing private information, or being manipulated through hidden instructions embedded in the material they process. Problems can also emerge from the way AI handles memory, follows instructions, and interacts with external services.
This, F-Secure argues, weakens the idea that consumers can protect themselves simply by staying alert or checking suspicious outputs. In many cases, meaningful protection has to be built upstream into the systems that create, host, and connect AI tools.
Access problem
A central conclusion of the research is that opportunities to intervene are limited for independent researchers and security providers because they often lack access to the systems where safeguards would be most effective. That creates a gap between those who identify risks and those able to put controls inside AI products and connected services.
F-Secure suggests one answer would be a standardised interface that allows external security tools to inspect AI outputs and block harmful actions before they occur. It compares the idea to standardised car seat anchor points, where a common design makes independent safety equipment easier to install and use.
The taxonomy forms part of the company's broader work on consumer protection in AI-based services. F-Secure says the research supports its efforts to address trust, deception, and resilience as AI becomes more embedded in everyday digital activity.
The study groups the 26 harms into five relationship types in an effort to show how different interactions between users, AI systems, and connected services can create different risks. By sorting those paths, the framework aims to identify whether a defence belongs on a consumer's device, within an AI model, in a memory system, or in another linked service.
For businesses developing AI products, the work adds to pressure to define responsibility more clearly as systems become more autonomous. For security companies and independent researchers, it also highlights a practical limitation: they may see where harm occurs but still have little visibility into the internal systems where it could be stopped.